In-Depth
Stop Blaming the VM: How DEX and XLAs Pinpoint the Real Root of Bad User Experience
I recently sat down (virtually) with Maurice van den Driessche, senior solution consultant at Nexthink, to talk about one of the newest topics in VDI and EUC: Experience Level Agreement (XLA). We discussed XLA in general and XLA with VDI specifically. Below is my summary of that conversation.
Why XLA
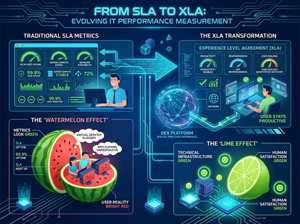
For as long as we have been setting up enterprise infrastructure, Virtual Desktop Infrastructure (VDI) and remote workstations, IT administrators have relied on the Service Level Agreement (SLA). You set up hypervisors, allocate virtual machines, monitor server compute and keep host uptime hovering around 99.9%. On paper, everyone is happy, as all the metrics across the dashboard show green.
Yet when you talk to end users on the ground, they tell you their virtual desktop feels sluggish and applications are unresponsive.
This is the "watermelon effect": an environment that looks completely green on the outside by the metrics but is bright red on the inside, where users are trying to get their work done.
Bridging this divide requires a fundamental change in how we measure desktop performance. Enter the Experience Level Agreement (XLA).
In traditional IT operations, an SLA tracks reliability by measuring service availability, network packet delivery, ticket response windows and raw infrastructure uptime. An XLA takes a different tack. Instead of asking whether a server or session stayed operational, an XLA measures human and business outcomes. It assesses whether the digital workspace enabled the worker to stay productive, how responsive the application felt during actual task execution and other quantitative measures of users' experience.
 [Click on image for larger view.]
In modern end-user computing (EUC) and Digital Employee Experience (DEX), an XLA transforms subjective feedback and objective technical metrics into business benchmarks. It takes raw performance data from devices and networks, combines and cross-references it with actual user sentiment, and helps deliver what can be described as the "lime effect" -- an environment where the technical infrastructure and human satisfaction are green on the inside as well as the outside.
Tackling the Silo Problem in VDI and End-User Environments
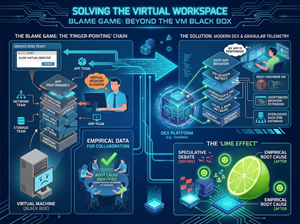
Whenever performance degrades in a virtual workspace, end users blame the virtual machine (VM) itself. As anyone who has spent time troubleshooting hosted desktops knows, VDI has historically been an easy target for finger-pointing. If an enterprise resource planning tool hangs or an internal webpage is slow to respond, the user complains, and the service desk files a ticket stating the virtual desktop is "slow," as that is their access point to the virtual environment.
End-user delivery is an intricate, multilayered chain: endpoint client hardware, local network routing, wide-area transport, hypervisor resource scheduling, storage latency and internal application performance. When users complain that "VDI is slow," it is rarely the underlying ESXi hypervisor, Hyper-V host or AHV node running out of compute; it is almost always client-side Wi-Fi latency, misconfigured display protocol policies (Blast/PCoIP/HDX) or profile disk bloat. Without comprehensive metrics, the finger-pointing begins; the storage team blames the network engineers, the network team points at the hypervisor admins, and the desktop administrators are left holding the bag.
Modern DEX platforms, such as Nexthink, collect granular metrics across this delivery chain. Rather than treating the virtual machine as an isolated black box, these monitoring engines look at real-time application behavior directly inside the session. IT can immediately distinguish whether a performance drop stems from a noisy neighboring VM, an unoptimized browser extension or an overloaded back-end database.
 [Click on image for larger view.]
This is critical for bringing cross-disciplinary teams together to solve the problem, not to shift the blame. When you tie infrastructure diagnostics to an XLA, you replace speculative debates with empirical data. You identify the exact root cause of disruption rather than continuously mopping up symptoms after the fact.
Aligning Technical Metrics With Business Realities
Implementing XLAs forces IT departments to confront an uncomfortable question: when is system performance simply good enough?
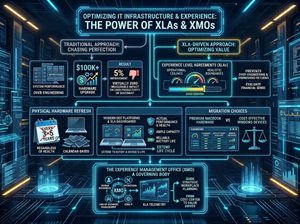
Infrastructure architects often waste their time chasing marginal hardware and hypervisor optimizations. It is entirely possible to spend $100,000 overhauling a SAN or compute cluster to shave five percent off load times, only to realize the upgrade produced virtually zero measurable improvement in user productivity or sentiment.
XLAs take a different approach by establishing an operational ceiling that protects organizations from overengineering solutions that deliver diminishing returns. They define realistic boundaries based on actual business needs, allowing management to evaluate whether further capital investments make financial sense.
This balance becomes obvious when evaluating physical hardware refresh cycles for end-user devices. IT departments have traditionally relied on calendar-based depreciation schedules, replacing laptops and workstations every three to five years regardless of health.
With modern DEX platforms feeding XLA dashboards, organizations can manage hardware based on actual performance and health rather than arbitrary calendar dates. If data shows an existing fleet still has ample processing capacity and reliable battery life for a user's workflow, IT can comfortably extend the machine's deployment life without sacrificing end-user performance or increasing help desk calls.
Similarly, when businesses weigh migration choices, such as whether to purchase premium MacBook hardware or deploy cost-effective Windows devices, XLA dashboards let executives compare hardware costs, support ticket frequency and the all-important worker sentiment before committing budget to solve a perceived problem.
 [Click on image for larger view.]
Rather than treating digital workspace delivery purely as a cost center, organizations are increasingly establishing a dedicated governing body: the Experience Management Office (XMO). This office brings together stakeholders from human resources, operations, line-of-business management and core IT; the XMO acts as a governing body that reviews XLA telemetry to guide strategic workplace planning.
Integrating Sentiment, Governance, and Pragmatic Automation
Telemetry alone, however, reveals only half the picture. A device might show excellent resource utilization while the person sitting in front of it is thoroughly frustrated because an application is slow, a critical peripheral has failed or a legacy workflow has broken.
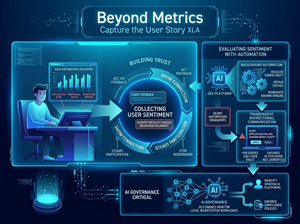
Capturing sentiment is essential to an XLA, but it requires moderation and discipline. High-volume, untargeted polling breeds survey fatigue and craters response rates. More importantly, sentiment collection is an implied contract: if users see that their feedback triggers remediations, like a repaired profile cache or boosted vCPU allocations, they will continue engaging. If their tickets vanish into a black hole, they check out entirely and will not respond to future surveys.
Furthermore, to build trust, organizations must act on the feedback they receive and show a connection between reported issues, technical improvements and improved end-user performance. If users realize that their input drives tangible infrastructure improvements, survey participation rates will remain steady. On the other hand, if no action is taken on surveys, users will stop responding.
This sentiment data becomes even more valuable when evaluated alongside automated remediation. Modern DEX and operational platforms leverage background automation to resolve configuration drift, repair corrupt caches and remediate known errors without administrative intervention.
Yet IT professionals know that silent automation can sometimes cause as many headaches as it cures. In enterprise deployments, transparent, bidirectional communication, such as using an integrated platform to alert a user that an application is stalling and ask for confirmation before applying a script, preserves end-user trust and ensures automated scripts do not disrupt active work.
 [Click on image for larger view.]
Furthermore, as artificial intelligence applications and local AI utilities become standard enterprise tools, AI governance becomes critical. DEX engines can monitor local workstation workloads to identify shadow AI platforms and enforce compliance policies.
Moving Beyond the Operational Silo
Across the broader end-user computing market, operational isolation is no longer sustainable. Managed Service Providers (MSPs) and systems integrators are shifting from traditional SLA contracts to XLA-based deliverables because enterprise customers demand transparency into real-world service outcomes.
Organizations like the XLA Institute are working to formalize standardized methodologies, and the emerging ISO standard for XLAs will help establish unified definitions across an industry that has long struggled with inconsistent terminology.
As enterprise platforms incorporate advanced DEX operational frameworks (DEXops), the goal is no longer just keeping servers online. The objective is to create a responsive digital workspace that reliably supports end users without getting in their way. Moving past the surface-level green metrics of legacy SLAs toward data-driven XLAs is a necessary step for any organization serious about modern end-user computing.
Special thanks to Maurice van den Driessche for taking the time to share his insights on the evolving role of XLAs and DEX in modern VDI architectures.
 [Click on image for larger view.]
Event Information: Nexthink's premier annual conference, Experience '26, will take place in Orlando, Florida, from October 5--7, 2026, at the JW Marriott Orlando, Grande Lakes. For full agenda details, keynote speaker tracks and registration, visit Nexthink Experience 2026.
About the Author
Tom Fenton has a wealth of hands-on IT experience gained over the past 30 years in a variety of technologies, with the past 20 years focusing on virtualization and storage. He previously worked as a Technical Marketing Manager for ControlUp. He also previously worked at VMware in Staff and Senior level positions. He has also worked as a Senior Validation Engineer with The Taneja Group, where he headed the Validation Service Lab and was instrumental in starting up its vSphere Virtual Volumes practice. He's on X @vDoppler.